Quick answer
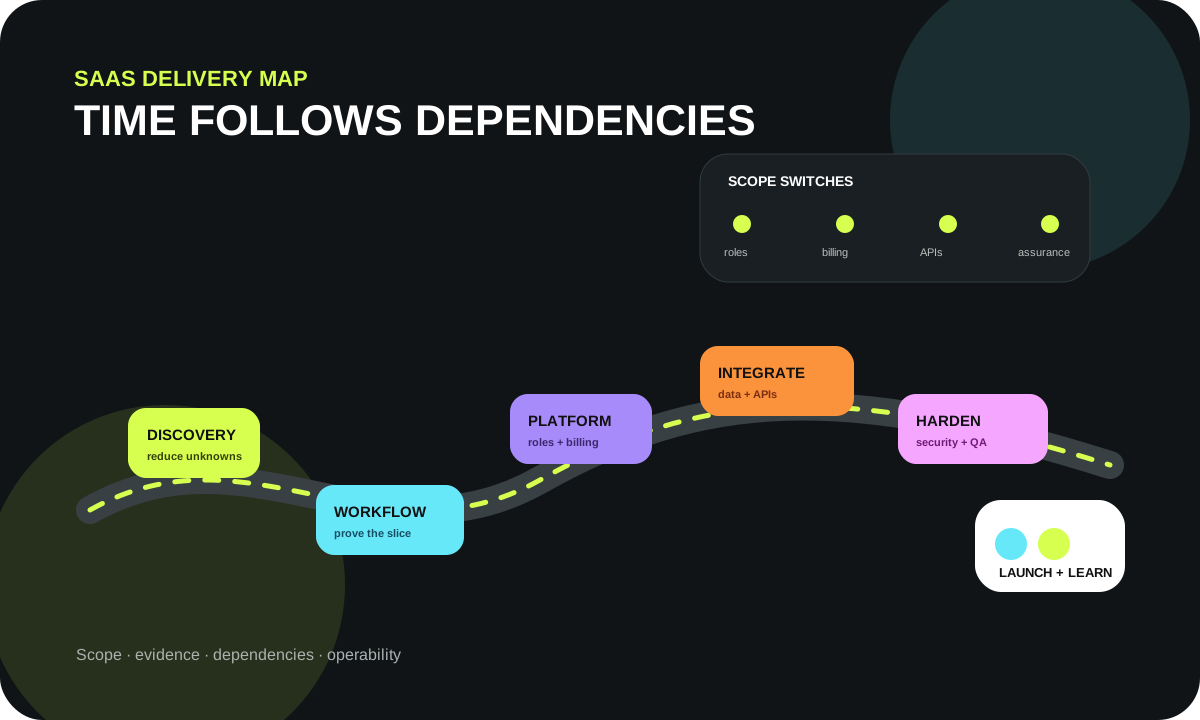
Estimate SaaS by the first releasable user outcome plus the production obligations around it. Narrowing workflows and dependencies can shorten the plan; deleting security, data-integrity or operability work only moves risk later. Use the planner to expose phase pressure, then translate delivery cycles into calendar time with your actual team capacity, review cadence and dependency dates.
Last reviewed: 2026-10-06T00:00:00.000ZSaaS delivery-cycle planner
Use six scope inputs to expose relative delivery effort and critical-path pressure. The model uses disclosed WebDesignK editorial coefficients; it does not predict calendar weeks, staffing productivity, price or a guaranteed launch date. Translate the output into calendar time only after you know team capacity, review cadence and external dependency dates.
1. Phase roadmap by relative effort
The bar changes with your inputs. It shows where the model allocates attention, not elapsed calendar time.
2. Scope-pressure heatmap
Darker cells flag inputs that create more dependency or verification pressure in this scenario.
3. Cumulative effort curve
The curve visualizes how modeled effort accumulates across the six phases.
- 1Discovery
- 2Workflow prototype
- 3Core platform
- 4Data & integrations
- 5Security & QA
- 6Launch & learn
Tailored next-step checklist
- Freeze the first releasable workflow: 2 core workflows currently selected.
- Prototype the riskiest 1 integration before committing the full schedule.
- Verify team permission boundaries with representative tenant and role data.
- Exercise the subscription billing/entitlement lifecycle before release if it changes access.
- Rehearse none migration/reconciliation and rollback expectations.
- Define baseline assurance evidence, monitoring owner and launch rollback criteria.
Assumption note: coefficients and delivery-cycle bands are transparent editorial planning devices. They are not sourced averages, contract estimates, staffing forecasts or promises. Use the official security/operations sources in this article to define evidence, then estimate against your actual team and dependencies.
Tables built for the buying decision
Primary decision table
| Decision | Option | Benefit | Tradeoff | Effort | Best fit |
|---|---|---|---|---|---|
| First release boundary | One vertical workflow | Fastest route to real evidence | Leaves adjacent workflows manual or deferred | Lower | Early validation and constrained teams |
| First release boundary | Several connected workflows | More complete customer journey | More states and integration points before learning | Higher | Known domain with stable requirements |
| Permission model | Simple account / one role | Smaller authorization surface | May not support team or enterprise buying | Lower | Single-user or simple workspace product |
| Permission model | Tenant + granular roles | Supports collaboration and enterprise controls | More negative authorization paths to design and test | Higher | B2B teams and delegated administration |
| Billing | Standard subscription | Clear entitlement lifecycle | Still requires retries, cancellations and access rules | Medium | Straightforward paid SaaS |
| Billing | Usage / metered entitlements | Supports consumption-based commercial model | Metering, reconciliation and edge states add system complexity | Higher | Products whose value maps to measurable usage |
| Integration strategy | Prototype risky API first | Retires a critical unknown early | May produce throwaway code | Medium | Products dependent on external systems |
| Migration strategy | Reversible staged migration | Improves reconciliation and rollback confidence | Needs mapping, tooling and validation work | Higher | Existing customer/history import |
| Assurance | Baseline production controls | Keeps initial evidence focused | May not satisfy enterprise procurement | Medium | Early and mid-market release |
| Assurance | Formal / audited evidence | Supports higher-assurance buyers | Adds review, documentation and verification lead time | Higher | Enterprise, regulated or contractual requirements |
Implementation checklist
| Owner | Evidence | Status |
|---|---|---|
| Product | First releasable workflow, in/out boundary and decision log | Not checked |
| Engineering | Architecture decision records for high-cost-to-reverse choices | Not checked |
| Security | Authorization negative tests and agreed verification evidence | Not checked |
| Integration owner | Sandbox credentials, failure cases, retries and reconciliation plan | Not checked |
| Data owner | Representative migration sample, mapping and rollback/reconciliation evidence | Not checked |
| Billing owner | Entitlement lifecycle tests including cancellation/refund/change states | Not checked |
| Operations | Logs, metrics, alerts, runbook and recovery/rollback owner | Not checked |
| Delivery lead | Dependency dates, review cadence and launch-blocker register | Not checked |
Turn this planning result into a scoped review.
Send the assumptions, constraints and result summary. WebDesignK can review the architecture/content/implementation boundary, identify missing discovery inputs and return a prioritized next-step scope.
- Bring: current site/product, constraints, integrations and your tool result.
- You get: a scoped recommendation, open questions and implementation priorities.
There is no defensible universal number of weeks or months to build a SaaS product. A narrow first release with one core workflow, simple permissions and few dependencies can move through delivery cycles much faster than a product with multi-tenant isolation, billing, migration, enterprise identity and audited controls. The useful estimate comes from scope, dependency depth, decision speed and release evidence—not screen count. Start with a releasable learning loop and make uncertainty visible before promising a date.
What you'll learn / decide
- Which scope choices move a SaaS schedule most
- How to separate prototype speed from production readiness
- Which inputs must exist before a schedule deserves confidence
- How to detect the most expensive timeline failures early
- What to measure before and after launch so the plan improves
Decision snapshot for How Long Does It Take to Build a SaaS Product?
The single most important tradeoff is breadth versus confidence. You can usually make a schedule shorter by narrowing the number of workflows, integrations, roles, migration obligations or assurance requirements in the first release. You cannot safely make a schedule shorter by pretending those obligations do not exist.
A useful plan therefore has two boundaries. The first is the product boundary: which user outcome must work end to end? The second is the production boundary: what must be true for that outcome to be safe, supportable and observable in the environment where customers will use it? A prototype may answer a product question without satisfying every production obligation. A launch cannot.
Decision trigger: prioritize timeline planning when a date starts influencing hiring, fundraising, customer commitments, procurement, marketing launch plans or contractual expectations. That is the moment a vague backlog becomes financially expensive. If stakeholders are already discussing a launch month while tenancy, identity, migration, billing or integration ownership are unresolved, the schedule has more certainty than the underlying system.
Use the interactive planner above as a pressure map, not a promise. It returns delivery-cycle planning units from your inputs so you can see where effort shifts. Convert those units into calendar time only after you know actual team capacity, review cadence, holidays, external vendor dates and approval constraints.
Executive quick answer
A SaaS build takes as long as it takes to retire the risks required for the first releasable outcome. The fastest credible route is usually a narrow vertical slice: one real user, one meaningful job, representative data, production-like authorization and enough observability to learn safely. That slice creates evidence. Additional workflows can then be estimated from something real instead of from a feature list.
Prototype, MVP, production release and enterprise readiness are different milestones
A prototype is allowed to be disposable. Its job is to answer a question such as “Can users complete this workflow?” or “Can this integration support the data we need?” A prototype can use fake data, manual operations or simplified infrastructure when those shortcuts do not invalidate the question.
An MVP should be the smallest product capable of testing a business hypothesis with real use. It still needs enough quality to avoid learning the wrong lesson. If users abandon the product because authentication is broken or data disappears, you did not validate the idea—you validated a defect.
A production release adds operational responsibility: deployment, monitoring, access control, backup/recovery expectations, support paths, incident handling and controlled changes. An enterprise-ready release may add SSO, delegated administration, auditability, procurement evidence, contractual controls, data residency or formal security review. Those requirements are not cosmetic “later” items when they are required to close the customer you are targeting.
Why screen count is a weak schedule proxy
Two products with ten screens can have radically different delivery programs. A CRUD dashboard with one role and no migration is not comparable with ten screens that coordinate multiple tenants, metered billing, external APIs, background jobs and approval workflows. The schedule lives in states, permissions, dependencies and failure recovery—not only in visible pages.
When this problem becomes expensive
Poor timeline planning becomes expensive when a date is treated as fixed while the assumptions behind it remain fluid. Teams respond by adding parallel work, carrying more work in progress and postponing invisible quality tasks. That often creates the appearance of speed before integration, then a long tail of rework near launch.
The coordination tax appears before the code bottleneck
Adding people can increase throughput when work is genuinely separable. It can also increase review queues, merge conflicts, product decisions and communication overhead when the system is tightly coupled. A team building identity, billing and a shared domain model cannot always parallelize safely just because the deadline is close.
Schedule risk also comes from stakeholders. If a product owner can decide within hours, a question may stay off the critical path. If the same question requires legal, security, finance and customer review, the elapsed time can exceed the engineering effort. Track waiting time separately from build effort.
Unpriced dependencies create false confidence
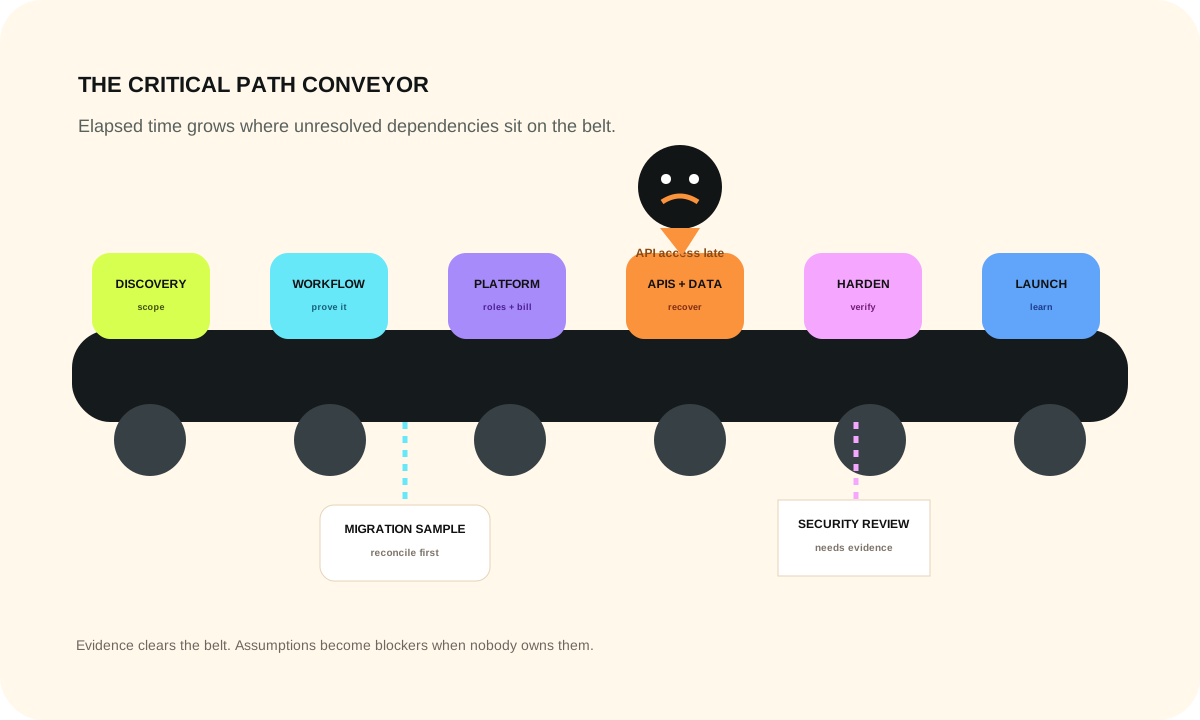
External identity providers, payment processors, customer APIs, data exports, DNS, legal approval and procurement onboarding can all sit outside the engineering team's direct control. A responsible plan names those dependencies, their owner, the date they are needed and what fallback exists if they are late.
A schedule should become more confident over time. If the launch date stays equally certain while scope and dependencies keep changing, the process is hiding uncertainty rather than managing it.
Decision criteria and constraints
Before estimating, define the few decisions that materially change architecture or acceptance work. This is where a short discovery document can save weeks of false starts.
Inputs required before a credible plan:
- A named primary user and the first end-to-end job they must complete.
- A workflow map showing happy path, key exceptions and who owns each state.
- A role/tenant matrix describing who can see and change which data.
- A list of external systems, API ownership, sandbox access and failure expectations.
- Billing and entitlement rules if money changes product access.
- Migration sources, sample data, reconciliation rules and rollback expectations.
- Security, contractual or regulatory requirements that need evidence before launch.
- A release owner, decision owner and review cadence.
Make hard-to-reverse choices earn stronger evidence
Not every decision deserves the same ceremony. A label color is reversible. Tenant isolation strategy, identifier design, billing event semantics or an irreversible data migration can be expensive to change after real customers exist.
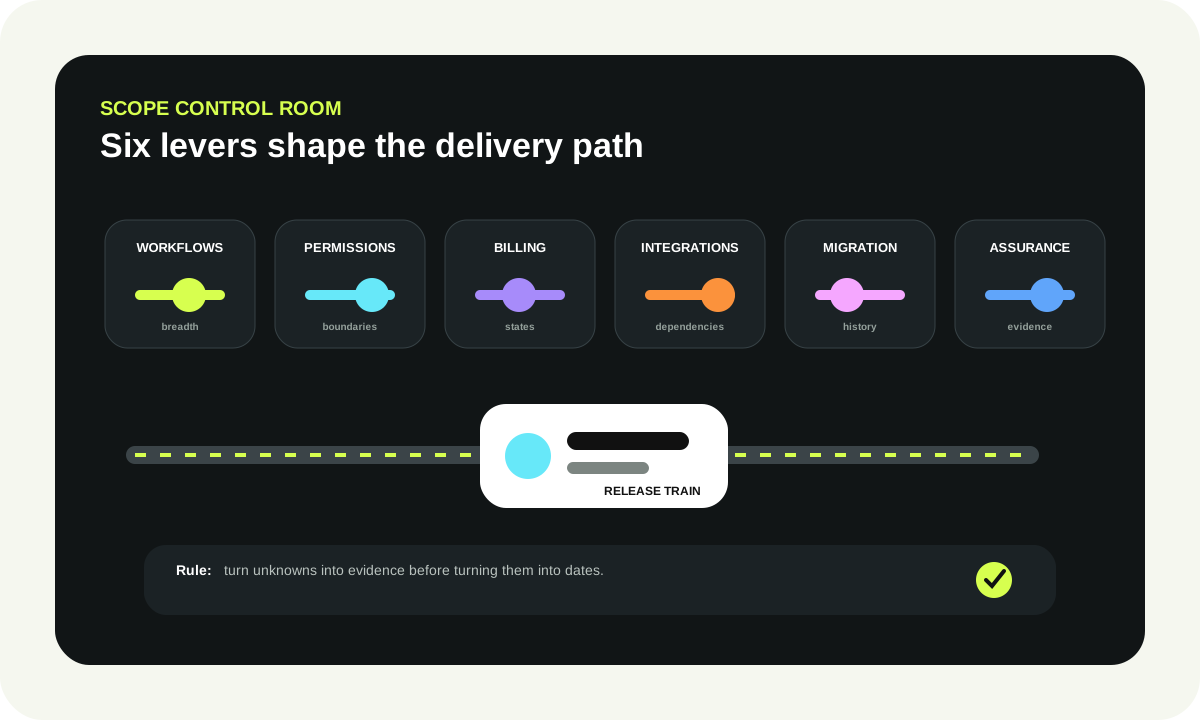
Use a simple rule: the higher the cost of reversal, the stronger the evidence required before implementation. Evidence can be a spike, a representative data sample, an architecture decision record, a failure-mode test or review by the person accountable for the risk.
Use the decision table before debating dates
The primary decision table above is intentionally qualitative. “High effort” does not mean an industry average number of hours. It means the choice introduces more states, verification or operational ownership than the simpler option. Use it to identify where discovery should go deeper, then estimate with the team who will actually deliver the work.
Recommended approach step by step
The most reliable SaaS schedule is built by retiring uncertainty in the same order that uncertainty can invalidate later work.
1. Frame the first business outcome
Write the first releasable outcome as an observable result, not a feature list. “A customer administrator can invite a teammate, assign a role, complete the core job and see the result” is easier to test than “build user management, dashboard and notifications.”
Define success and failure. What proves the workflow works? What data must remain correct? Which user should be blocked? What happens if an external service is unavailable? These acceptance statements become both design inputs and test cases.
2. Spike the riskiest dependency
If the product depends on an unusual API, large import, enterprise identity, document processing or a billing state that the team has not implemented before, prototype that dependency early. Do not spend a month polishing surrounding UI only to discover the critical integration cannot satisfy the contract you assumed.
A spike is not a production shortcut. It is a bounded experiment designed to turn an unknown into evidence.
3. Build a thin vertical slice
Connect UI, domain logic, persistence, permissions, logging and deployment for one meaningful flow. A thin slice exposes integration seams while change is still cheap. It also gives product and engineering a shared artifact for future estimation.
4. Expand workflows without losing operability
Once the first slice is stable, add adjacent workflows in small increments. Keep migrations, observability, tests and release automation moving with the product. Avoid the pattern where “feature complete” arrives first and all production work is moved into a final hardening phase.
5. Use exit evidence for every phase
A phase is complete because evidence exists, not because the calendar says it should be. Examples include an approved scope boundary, authorization tests, reconciled migration sample, billing lifecycle test, monitored staging release, restore exercise or signed security acceptance.
Scenarios by company stage
Company stage changes which uncertainty matters most. It does not remove the fundamentals of reliable delivery.
Early product: optimize for learning without creating a dead end
An early team should keep the first workflow narrow and may use manual operations behind the scenes. Manual review, concierge onboarding or a human-triggered export can be legitimate if they are visible and do not create unsafe data handling.
The trap is confusing temporary operations with missing ownership. If a founder manually fixes failed imports, record that as an operational process and decide what volume or risk should trigger automation.
Growth product: reduce operational friction and state complexity
Growth usually adds roles, billing changes, reporting, notifications, integrations and support tooling. The risk moves from “Can we build the workflow?” toward “Can we operate many customers safely and explain what happened when something fails?”
Admin tooling belongs in the schedule here. If support staff need engineers to change a subscription, retry a job or inspect a tenant, day-two work will compete with product development.
Enterprise selling: evidence becomes part of the product
Enterprise customers may require SSO, audit logs, security documentation, data-handling commitments, procurement forms or formal assurance evidence. Those activities have lead time and stakeholders beyond the feature team.
Do not call them “sales tasks” and exclude them from the launch plan when they determine whether the intended customer can actually buy and use the product.
Technical/operational considerations
A SaaS product is a continuing service, not a shipped executable. The schedule should include the mechanics that keep data and access correct after the first deployment.
Tenancy and authorization need server-side boundaries
Role checks that exist only in the UI are not authorization. Define tenant and role boundaries where data is read and written. Test negative cases: user from tenant A requesting tenant B data, former member retaining a stale token, background job running with the wrong scope, or admin action bypassing normal policy.
The exact implementation depends on architecture; the acceptance principle is stable: access decisions must be enforceable and testable independently of presentation.
Billing is a lifecycle, not a checkout button
Subscriptions can create states such as trial, active, past due, canceled, refunded or changed plan. Usage models add metering, aggregation and reconciliation. Decide which events affect entitlements and what happens when billing providers retry or deliver events out of order.
If billing changes access, it belongs in the product state model early enough to test—not as a last-week integration.
Integrations need failure behavior
A successful API demo proves only the happy path. Production integrations need timeouts, retries where safe, idempotency, rate-limit handling, schema change detection, observability and a way to reconcile partial failure.
Operability should be designed with the workflow
Google's Site Reliability Engineering guidance emphasizes monitoring symptoms that matter to users and operators rather than collecting metrics without a purpose. For your SaaS, define what “healthy” means for the first workflow: can users authenticate, complete the job, receive a result and recover from failure? Logs, metrics and alerts should help answer those questions.
NIST's Secure Software Development Framework and OWASP's Application Security Verification Standard are useful references for organizing secure-development and verification practices. Neither provides a SaaS delivery-time benchmark. Use them to define work and evidence, not to manufacture a duration.
Common mistakes and warning signs
Three expensive failure modes to detect early:
1. Estimating an undefined backlog as if it were a specification
Warning signs: dozens of features with no first user outcome, no in/out boundary, and estimates that assume every item is equally independent. Detection test: ask the team to describe the first deployable vertical slice and what can be removed without invalidating it. If nobody agrees, the schedule is premature.
2. Discovering production obligations after feature work
Warning signs: permissions described as “later,” billing states absent from the domain model, no migration sample, no monitoring owner, or security review booked after the target launch date. Detection test: create a launch evidence checklist before implementation and assign every item an owner.
3. Treating external dependencies as engineering tasks with guaranteed dates
Warning signs: API access “should arrive,” enterprise SSO metadata “will be provided,” legal review has no named reviewer, or customer data exports have never been sampled. Detection test: put every external dependency on the plan with a needed-by date, owner and fallback. If no fallback exists, it is on the critical path.
Other warning signs include a growing number of long-lived branches, test environments that differ materially from production, shared databases without realistic tenant data, and a release plan whose only rollback strategy is “fix forward.”
How to evaluate implementation options
A credible delivery partner should make uncertainty legible rather than hide it behind a confident date.
Compare evidence, not just velocity claims
Ask how the team will prove tenant isolation, migration correctness, billing lifecycle behavior, integration recovery, deployability and observability. Request examples of architecture decisions, test strategy, release process and operational handover—not proprietary client data, but the shape of the evidence they use.
A fast prototype is valuable. It demonstrates execution and can retire uncertainty. It is not proof that production obligations are complete.
Match the commercial model to uncertainty
Fixed scope is easier when acceptance criteria and dependencies are stable. Time-and-materials can fit exploratory product work where learning changes the backlog. A discovery phase can be useful when neither side can responsibly price the unknowns yet.
The contract should not pretend uncertainty disappears. It should define how discoveries change scope, who decides and what evidence is required.
Keep ownership visible after launch
Ask who owns monitoring, support, infrastructure changes, security updates, backups, dependency upgrades and integration failures. If the delivery model ends at deploy time, your internal team needs an explicit takeover plan.
For a scoped technical review, see Custom SaaS Development. For related planning decisions, compare SaaS MVP cost, multi-tenant architecture tradeoffs, and build versus buy.
Timeline and measurement plan
A useful timeline measures both delivery progress and uncertainty retirement. Story count alone can rise while launch confidence falls.
Leading indicators
Leading indicators tell you whether the plan is becoming more credible:
- Percentage of launch-critical decisions with a named owner and accepted evidence
- High-risk integrations tested with realistic credentials and failure cases
- Representative migration samples reconciled successfully
- Critical authorization paths covered by automated and negative tests
- Deployment frequency and staging-to-production parity
- Open launch blockers by severity and age
- Review turnaround time for product, security, legal or customer decisions
These are operational indicators for your own program, not universal benchmarks. Set thresholds from your risk tolerance and delivery process.
Outcome metrics
Outcome metrics should connect the release to the user and business outcome that justified it. Depending on the product, this may include successful completion of the core workflow, activation, retained usage, support burden, error rate, paid conversion or time saved in an internal process. Choose metrics that can actually falsify the hypothesis.
Do not declare an MVP successful because it shipped on the planned date. A schedule is an input to learning, not the learning itself.
Review cadence
Use a review cadence that matches how quickly meaningful evidence changes. During active delivery, a weekly risk and dependency review may be appropriate for many teams; a highly constrained program may need more frequent coordination around specific blockers. After launch, review reliability and user evidence frequently enough to catch harm, then use a broader monthly review for roadmap and operating trends.
The key rule is that reviews change decisions. A status meeting that only repeats percentages is not risk management.
FAQ and next-step checklist
Can a SaaS MVP be built very quickly?
A narrow prototype or MVP can move quickly when the workflow, decisions and dependencies are small. “Quickly” is not a substitute for defining production obligations. If real users depend on the product, include the controls needed to keep their data and access correct.
Should architecture be finished before coding starts?
No. Resolve decisions that are expensive to reverse and prototype risky assumptions early. Let working vertical slices inform the rest. Overdesigning an imagined future can waste time; ignoring known hard boundaries can cause expensive rewrites.
When should security happen?
Throughout design and delivery. Use secure-development practices during implementation and explicit verification before release. Security work discovered only at the end has fewer safe options and more schedule pressure.
Does adding engineers always make launch faster?
No. Some work parallelizes; tightly coupled domain, integration and data work often requires shared decisions. Add capacity where interfaces are clear and work can be independently accepted.
What should happen immediately after launch?
Watch the core workflow, reliability and support signals. Verify that alerts are actionable, fix critical gaps, review real user behavior and reprioritize from evidence. Launch is the start of operating the product, not the end of the delivery system.
Next-step checklist
Before committing to a calendar date, confirm that the first releasable workflow is named, hard dependencies have owners, risky integrations have evidence, migration has a reconciliation plan, permissions have negative tests, billing states are understood, observability has an owner and rollback expectations are explicit. Then translate the planner's delivery-cycle scenario into your real team calendar.
Browse the SaaS Development hub for adjacent planning guides. If you want a second set of eyes, bring the planner summary and implementation checklist to a custom SaaS discovery conversation. The useful starting point is your constraints and evidence—not a preselected package.
Sources and assumptions
Last reviewed October 6, 2026. NIST SSDF, OWASP ASVS, Google SRE and web.dev are used here as authoritative references for secure development, verification, operations and browser performance. They do not publish a universal “SaaS takes X weeks” benchmark. The interactive planner, decision table and delivery-cycle bands are transparent WebDesignK editorial planning models. They are not quotes, productivity benchmarks, market averages or guarantees.
Frequently asked questions
Can a SaaS MVP be built very quickly?
A narrow prototype or MVP can move quickly when scope and dependencies are small, but production readiness is a separate question. Real users still need appropriate data integrity, access control and operability.
What makes SaaS timelines expand most?
Unclear product scope, tenant and permission complexity, billing, external integrations, migration, security evidence and slow cross-functional decisions are common schedule multipliers.
Should architecture be designed completely before coding?
No. Resolve high-cost-to-reverse decisions early, prototype risky assumptions, and let working vertical slices inform the rest.
When should security work happen?
Throughout design and delivery, with explicit verification before release rather than a single final scan.
Does adding engineers always reduce calendar time?
No. Some work parallelizes, while tightly coupled domain, integration and data work can create coordination overhead.
What should happen immediately after launch?
Monitor reliability and the core user outcome, review support and usage evidence, fix critical gaps and reprioritize the backlog from observed behavior.
Sources and assumption boundaries
Fast-changing platform, pricing and search claims were reviewed on 2026-10-06T00:00:00.000Z. Interactive scores and scenarios are clearly labeled planning models, not sourced market benchmarks.
- NIST — Secure Software Development Framework (SSDF) Secure-development lifecycle reference used to frame implementation and verification work; reviewed October 6, 2026.
- OWASP — Application Security Verification Standard Application security verification reference used for release-evidence planning; reviewed October 6, 2026.
- Google SRE — Monitoring distributed systems Operational monitoring concepts used for day-two planning; reviewed October 6, 2026.
- web.dev — Core Web Vitals User-centered browser performance guidance for SaaS experiences; reviewed October 6, 2026.


